Two researchers introduced RFBench on November 17 as a test for multimodal systems working with passive radio-frequency circuits. Each of 10,000 two-port layouts is represented several ways. A model can receive a specification, a rendered picture or editable geometric primitives, then be asked to generate a layout, translate representations, predict a response or diagnose a design. The response comes from electromagnetic simulation. The study’s central lesson is that these steps are related, but success in one does not establish success in the next. RFBench paper
Passive RF structures are parts that guide or shape high-frequency signals without active amplification. Transmission lines, matching networks, filters and antenna-tuning networks all depend on the physical arrangement of conductive metal. A small change in line width, gap, connectivity or port placement can change how energy reflects or passes through across a frequency range. Engineers therefore move repeatedly between a performance target, an editable layout and a full-wave electromagnetic simulation. A drawing can look orderly and still fail to connect electrically or produce the desired response.
That gap motivates a benchmark that joins language, geometry and physics. A multimodal model may recognise a familiar circuit picture or emit a correctly formatted set of rectangles. RF design asks for more. The rectangles must form a permitted structure, their geometry must match the intended representation, and the electromagnetic behaviour must meet the specification. Each of those statements has a different test. RFBench separates them into seven task families instead of allowing a single easy metric to stand in for the full design process.
One layout, several linked representations#
The data set contains 10,000 planar two-port layouts created by procedural geometry generators. Each accepted design has editable rectangles and ports, a rendered image, a 16-by-16 occupancy grid, a simulated complex scattering matrix, a structural category and a response label. A shared design identifier links the representations. This lets the benchmark ask whether a model can move between a symbolic description, a picture and a discrete grid while preserving the same metal geometry.
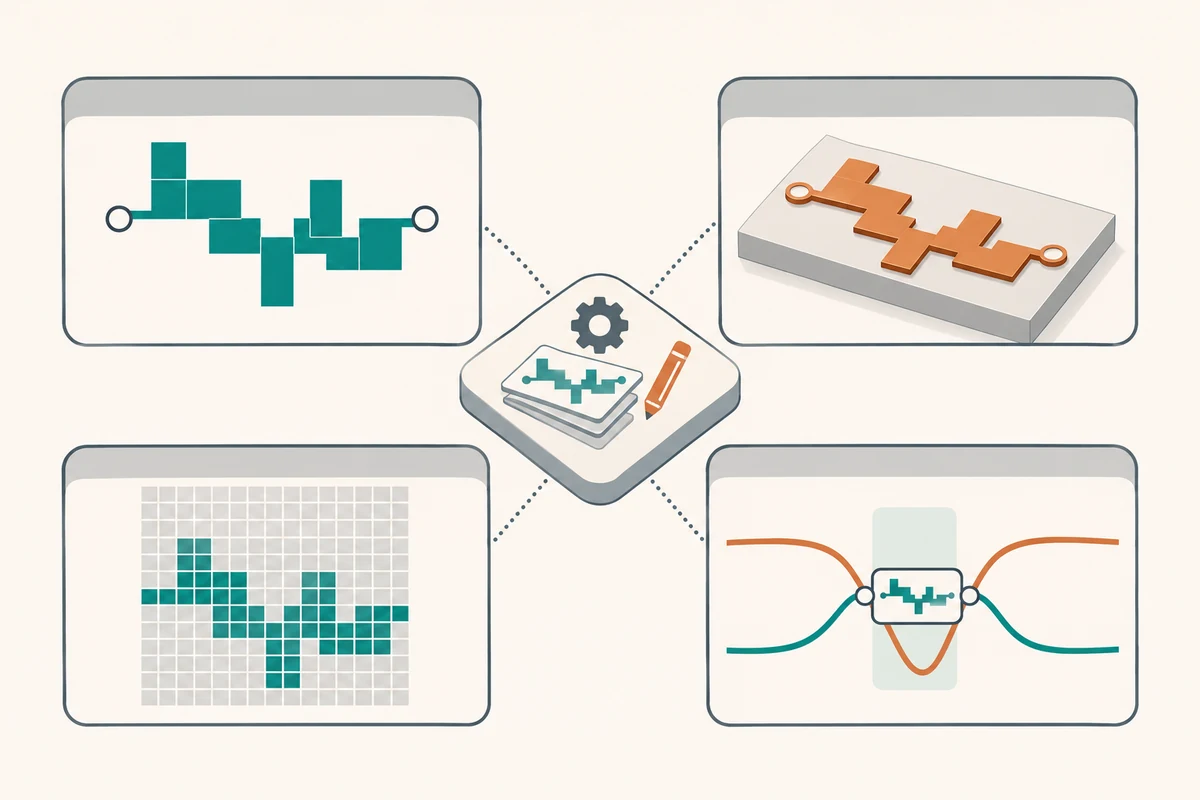
The five structural categories each contain 2,000 examples. They include randomly connected layouts, microstrip-inspired center traces with branches, 180-degree rotational symmetry, left-right mirror symmetry and top-bottom mirror symmetry. These are controlled construction families, not samples of every layout used in working RF products. They give the benchmark repeatable examples of connectivity, symmetry and geometric motifs that can be checked automatically.
Each layout is simulated with ADS Momentum at 201 equally spaced frequencies between 1 and 10 gigahertz. The data retain the full complex two-by-two S-parameter matrix. Those values describe reflection and transmission at the two ports as frequency changes. In practical design, the engineer cares about how the whole response curve behaves. The benchmark can therefore compare predicted values point by point and test physical properties such as passivity and reciprocity alongside ordinary numerical error. Dataset and simulation details
The dataset is generated, not measured from fabricated boards. Geometry generators produce candidate copper patterns, then automated checks reject layouts that do not satisfy required properties such as feed-to-feed connectivity, canvas limits or port conditions. Each of the five families is balanced in the retained design corpus. Response labels are imbalanced, with some types appearing rarely. The test reports class-balanced macro-F1 as well as accuracy for the response classifier, which helps keep common classes from dominating the story.
The official split keeps 9,000 designs for the training pool and 1,000 held-out designs for common-set evaluation. The held-out group contains 200 examples from each structural family. T1, T2, T3, T6 and T7 share these IDs, supporting paired comparisons across tasks. Simulator execution uses a balanced subset of 250 generated layouts, and the design-diagnosis task uses 100 shared cases. These are distinct test panels. The paper’s main results are not all based on the entire corpus.
The representation alignment makes failure diagnosis more informative. If a model turns editable rectangles into a wrong grid, the output identifies a symbolic conversion problem. If it reads a picture poorly but handles primitive geometry well, the difference suggests a visual perception gap. If both translations work and response prediction fails, the model has a different weakness. A single benchmark score would blur those explanations. RFBench keeps the intermediate tasks visible so the reader can locate the part of the engineering chain that breaks.
Seven tests follow a design workflow#
The first task group asks a model to generate a layout from a natural-language electrical specification. In one version the model receives target magnitudes for four S-parameters at three frequency landmarks. A second version also specifies a structural category. The generated output is an editable geometric layout. A validity score checks for two ports, containment on the canvas and a connected metal path between feeds. Category compliance is assessed separately when a category is requested.
The target values are taken from a simulated design, so a known geometry can realise each specification. The geometry itself is withheld, and the model does not need to rediscover the exact original. It can satisfy the same target with another valid arrangement. This distinction matters because a generative design test should assess the requested electrical behaviour and structural rules, not whether the model guessed a hidden source layout. The three frequency landmarks simplify the target presented to the model, while the later simulator test checks a fuller response sweep. The benchmark therefore separates a short specification prompt from validation across all measured frequency points.
Representation translation forms the second group. A model converts editable geometry into a binary metal occupancy grid, or converts a rendered image into the same grid. The 16-by-16 grid has 256 cells. Foreground precision, recall, F1 and intersection-over-union describe how many metal cells were mapped correctly. The paper also reports exact-grid match and normalized Hamming distance. This task isolates whether the layout’s shape survived a change in representation.
The third group predicts the electromagnetic response. A model receives primitives or an image and predicts the complex S-parameter sweep at 201 frequency points. Metrics include complex mean absolute error, the fraction of matrix-frequency points within two decibels, passivity-valid frequency rate, reciprocity error and spectral-derivative error. Those metrics describe different qualities. Pointwise closeness alone may overlook an unphysical response curve. RFBench task definitions
The fourth group runs a generated layout through ADS Momentum. Syntactically valid geometry may fail when imported into the simulator, so the test records run rate. It then asks whether the simulated values at three target frequencies satisfy all twelve specified S-parameter magnitudes within three decibels. A design that completes a simulation can still miss its electrical target. The separate numbers make that difference explicit.
Design diagnosis and improvement form the fifth task. The model receives a layout, its response and a target specification. It must decide whether improvement is needed and, where appropriate, propose a revised layout. The paper evaluates the decision with accuracy, precision, recall and macro-F1, then independently simulates redesigns. Target-error reduction and end-to-end improvement include invalid layouts and failed simulations in the outcome. An accurate diagnosis is one part of the task. The geometry must still change in a way that helps the actual design.
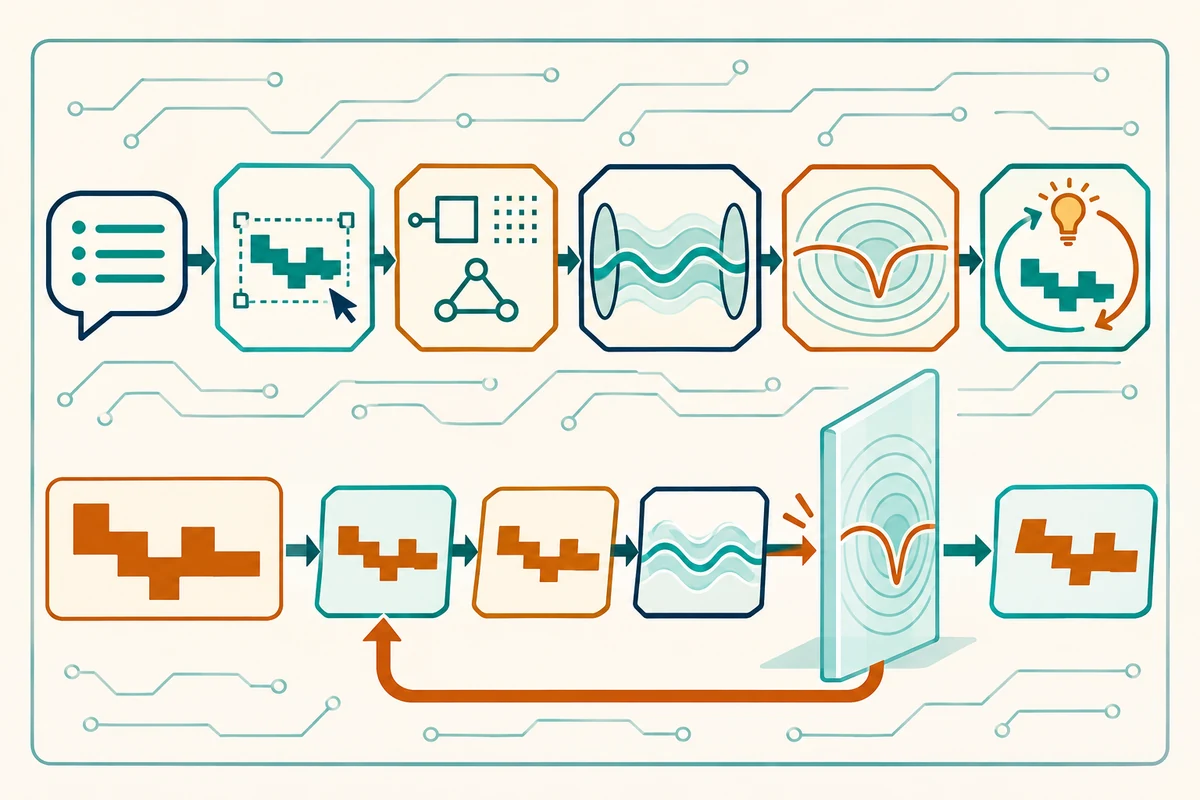
Structural understanding and response classification complete the suite. One test identifies the layout’s category and feature flags for properties such as symmetry and connectivity from primitives or a picture. Another classifies a simulated response as broadband through, broadband attenuating, low-pass, band-pass, band-stop or resonant-shaped. These tests ask whether a model can recognise properties of a layout and its output. They remain separate from creating a working design.
The authors do not treat one aggregate score as the main leaderboard. The tasks have different outputs, metrics and physical interpretations. Combining them into a single rank would require decisions about weights and trade-offs. An evaluator can instead read a profile. A model may parse shapes reliably and still predict the wrong response. Another may classify responses well while failing to produce a connected design. The disaggregated view is more useful when deciding which part of a design workflow could use model assistance.
Valid geometry is only the first gate#
Unadapted models frequently produced layouts that looked plausible while failing the combined structural checks. Several could place two port markers in nearly all cases, yet every unadapted baseline scored zero percent structural validity in specification-conditioned generation. Validity requires the ports, canvas and connected metal path to work together. A piece of geometry that passes a parser or contains two endpoints is not yet a usable RF layout.
RF-specific fine-tuning dramatically changed that result for Qwen3-VL-8B. Supervised fine-tuning reached 82.7 percent structural validity in one generation task and 86.0 percent in the category-constrained task. A reinforcement-learning stage with GRPO reached 83.2 and 86.4 percent. Full category compliance was 85.7 and 85.2 percent, respectively. These scores show that examples and task-specific adaptation can teach a model to meet the generated-layout contract. They measure structure, not successful RF behaviour.
The closed-loop simulator test exposes the next gap. Both adapted versions achieved a 100 percent ADS run rate on 250 generated layouts. Only 1.6 percent of SFT outputs and 2.8 percent of GRPO outputs passed the strict condition that all twelve target magnitudes fall within three decibels. The gap is instructive. Geometry can satisfy a structural rule and load successfully in a commercial simulator, yet miss the desired response. Inverse RF design remains much harder than creating syntactically and structurally valid metal.
This distinction matters for claims about engineering automation. If a model generates a layout that loads into ADS, it has passed an execution gate. It has not necessarily designed a filter, matching network or antenna structure with the promised performance. The requested target is a multi-frequency electrical behaviour. A design can have the right broad shape but the wrong reflection, transmission or bandwidth. A credible report keeps executable rate and specification-success rate separate.
The benchmark’s target specifications come from simulated designs, so at least one source geometry is known to realise each specification. Exact reproduction is not required. This creates a controlled inverse-design problem, but it also means success is evaluated within the generator and simulator’s represented design space. The authors describe the work as a benchmark for passive two-port layouts. A fabricated product can add material, manufacturing tolerance, packaging, connectors and measurement conditions that the current tasks do not include.
Similar-looking outputs can carry different physics#
The translation task is where domain adaptation has the strongest result. Unadapted models achieve foreground F1 up to 31.4 percent from primitive input and 48.2 percent from images. None produces an exact grid match. After RF-specific training, Qwen3 variants exceed 99.97 percent foreground F1 for both modalities, with exact-match rates between 99.0 and 99.5 percent. This is a near-saturated result on the benchmark’s discrete translation problem.
The success is meaningful, but it measures recovery of a 16-by-16 occupancy grid. It does not mean the model understands every electrical consequence of the metal pattern. The dataset and training pool share procedural families. The paper’s official held-out designs test new examples from those families, which provides an evaluation of generalisation within the generated corpus. Broader transfer to geometries and fabrication settings outside those generators remains an open question.
Response prediction remains harder. The strongest unadapted model, Claude 4.5, places 28.0 percent of primitive-input matrix-frequency points and 27.0 percent of image-input points within two decibels. Qwen3 SFT raises those values to 62.6 and 64.1 percent. GRPO changes them only slightly, to 62.8 and 64.1 percent. Complex prediction error also falls. The results show that supervised examples help, while the additional reward-optimisation step yields modest improvement for this task.
The physical checks complicate a simple accuracy ranking. Passivity-valid frequency rate measures whether the predicted network satisfies a physical bound. Reciprocity checks the expected relationship between forward and reverse transmission in the modelled structures. Spectral-derivative error considers how the response changes across neighbouring frequencies. One unadapted image model obtains 98.5 percent passivity validity while only 11.1 percent of points are within two decibels and reciprocity error is high. A response can therefore satisfy one physical check while being numerically inaccurate or collapsed.
After adaptation, the passivity-valid rate falls to about 72 percent, even as response accuracy, reciprocity and spectral consistency improve. A specialised CNN surrogate reaches the strongest pointwise accuracy in the reported comparison, with 84.4 percent of predictions within two decibels. Its passivity-valid frequency rate is 28.3 percent, and its reciprocity and spectral-derivative errors are higher than those of adapted language models. This is not one scoreboard with a clear winner. Each method combines physical and numerical properties differently.
The reward can teach a proxy that misses the final goal#
The diagnosis task makes the distinction between a good decision and a useful redesign visible. GPT-5.4-mini leads diagnosis at 89.0 percent accuracy and 88.4 macro-F1. SFT raises Qwen3-VL-8B diagnosis macro-F1 from 51.0 to 58.6 percent. GRPO reaches 55.5 percent. Yet end-to-end improvement after ADS simulation decreases from 48.4 percent for the backbone to 45.3 percent after SFT and 35.9 percent after GRPO. Median error reduction after adaptation is also close to zero.
The paper connects this mismatch to two parts of its training design. T5 diagnosis cases are excluded from SFT and GRPO, and GRPO uses rewards from a learned surrogate rather than running the full-wave simulator for every candidate. The system learns to improve the surrogate’s reward and can get better at structured predictions without producing more effective physical changes. The simulator result is a useful check on the reward’s connection to the task outcome.
This pattern recurs in AI engineering. A model can optimise the signal its training loop can afford to compute, while the product objective has a richer evaluation. A format check is cheaper than simulator execution. A surrogate can approximate full physics at lower cost. A reward that correlates with the desired outcome can accelerate learning, but the correlation must be measured on held-out cases and on the actual acceptance criterion. RFBench reports the mismatch instead of treating reward progress as design progress.
The response classification task also illustrates metric choice. After fine-tuning, accuracy rises above 94 percent, while macro-F1 is around 74 percent. Six response classes are imbalanced, with some rare types. Overall accuracy reflects common classes strongly. Macro-F1 gives each class a more visible contribution. Both values help explain model behaviour. Reporting only one would obscure the model’s weaker recognition of the infrequent response categories.
The benchmark’s physical scope stays specific#
RFBench focuses on simulated two-port planar layouts. It does not model fabrication constraints or measured physical devices. The 16-by-16 occupancy grid represents geometry within a small controlled design space, and ADS Momentum supplies the simulated response. This provides a repeatable link between layout and electromagnetics. Real production adds materials, fabrication tolerances, stack-up choices, packaging, connectors and measurement noise.
The data construction also defines what the model can learn. Five procedural geometry families each contribute 2,000 designs. A random design-disjoint split holds 1,000 for the official test set and 9,000 for the training pool. The authors report aligned examples across primitives, images, grids and responses, with checks for duplicate geometries and consistent rasterisation. These are useful corpus controls. A held-out random split still tests the same family generators, so it cannot establish performance on every topology an RF engineer might draw.
The authors say the dataset is released under CC BY 4.0 and code under MIT. At the time of checking the links provided in the paper, the GitHub address returned a 404 and the Hugging Face data page required authentication. Readers can inspect the paper and its reported results, while reproducing the dataset and code remains dependent on the linked materials becoming accessible. This availability status can change, so the benchmark’s release claim and the operational accessibility of its artifacts should be followed separately. RFBench paper and artifact links
The fine-tuning result also has a specific base model and training recipe. The authors apply RF-specific supervised fine-tuning and a GRPO stage to Qwen3-VL-8B. Strong improvements in the benchmark show that domain adaptation helps on its task families. They do not tell an organisation the cost of preparing equivalent data, the amount of improvement on its own RF toolchain or the transfer to commercial designs. Those questions need separate experiments and data aligned with the target workflow.
What engineers can learn from the score profile#
The most useful way to read RFBench is as a sequence of gates. A specification must be translated into geometry. The geometry must parse, fit the board and connect the feeds. A simulator must accept it. The response must match the frequency requirements and satisfy physical checks. Diagnosis must lead to a revision that reduces the actual error. An evaluation that stops at the first gate risks overstating the completed work.
The results suggest immediate places for engineering teams to focus. Constrained output schemas and exact geometry supervision can improve representation tasks. Simulator-backed evaluation is still necessary to measure electrical behaviour. Surrogate rewards should be checked against the full simulator on paired held-out cases. Class imbalance should be shown with macro metrics. Separate test splits are useful for generation, simulation and redesign when they have different costs and sampling needs.
There is also a model-selection implication. If a team needs to translate layouts or classify structures, the adapted model’s scores are encouraging within this benchmark. If the task requires meeting all electrical specifications, the strict success rate of 1.6 to 2.8 percent signals substantial distance. The choice depends on which stage the team intends to automate and what review remains around the output. A model that assists with a geometry representation may already be useful even when autonomous inverse design is not dependable.
RFBench’s authors provide seven tasks, common data representations and simulator-grounded measures for an area that previously lacked such a unified test. The clearest outcome is the separation between learned form and physical function. Models can learn to render a valid shape and nearly reproduce a discrete occupancy grid. Predicting a dense electromagnetic sweep is harder. Meeting every requested response value after simulation is harder still. That score profile is more informative than a claim that a model can design RF circuits.
The next evidence should come from publicly accessible artifacts, independent reruns, broader geometries and measured hardware. A simulator provides a reproducible physics model, but fabricated devices bring tolerances and parasitic effects that a synthetic dataset cannot settle. Teams can use the published design to examine where a model’s failure begins. The current benchmark establishes a useful testing structure and reports meaningful improvements from fine-tuning. Its strongest promise is as an instrument for locating gaps between a picture, a layout and a working high-frequency circuit.